LLMLingua [EMNLP'23, ACL'24] To speed up…
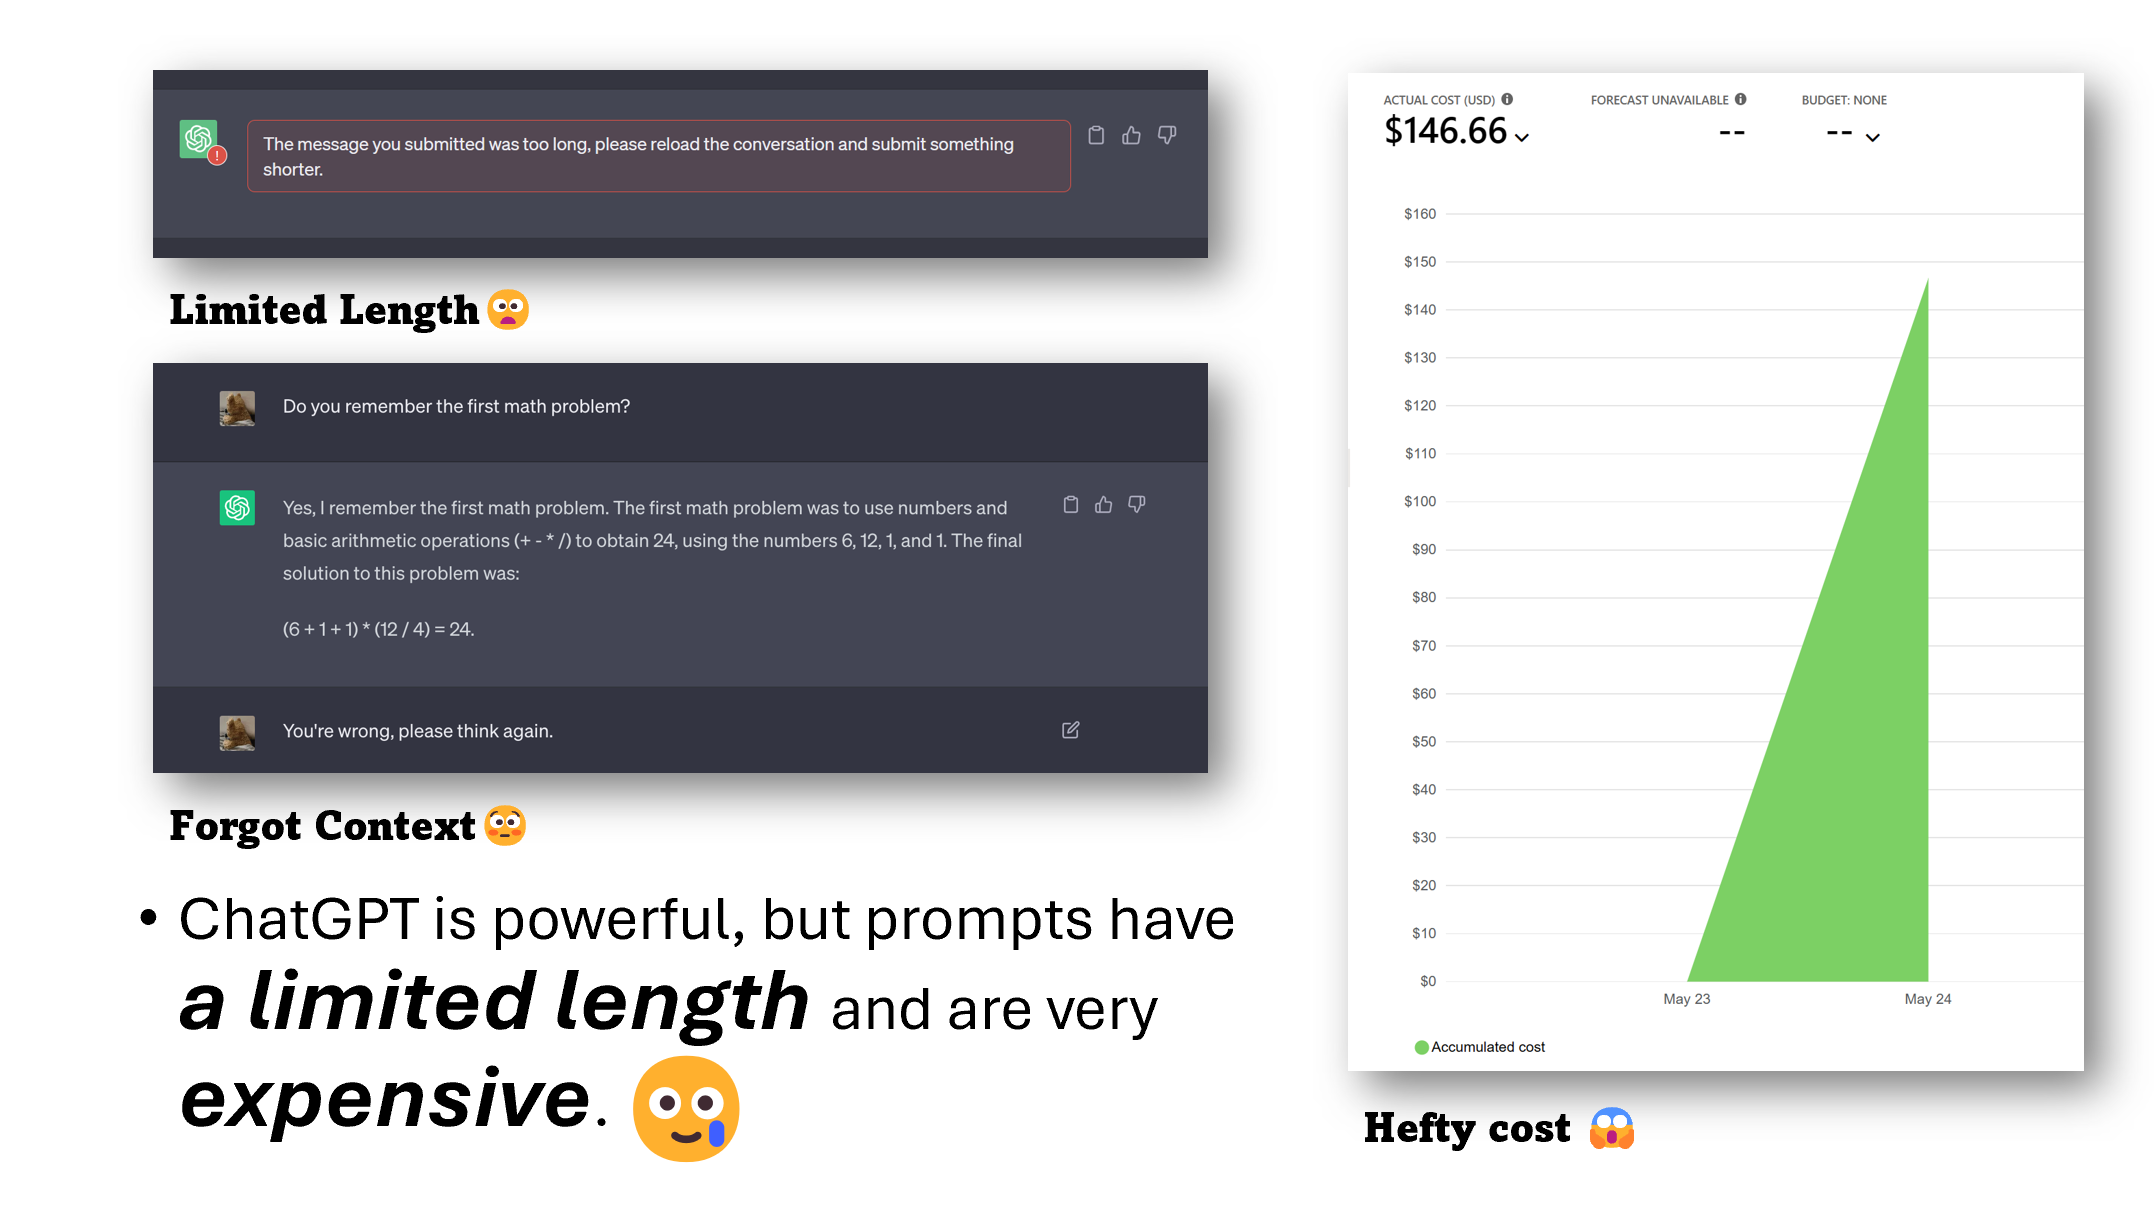
LLMLingua [EMNLP'23, ACL'24] To speed up LLMs' inference and enhance LLM's perceive of key information, compress the prompt and KV-Cache, which achieves up to 20x compression with minimal performance loss. Python · 6.8K · MIT · 最近更新 2026-11-06